131 of my 150 answers cited sources. My grader scored those citations 0.012 out of 1
I built a system that answers questions about research papers and cites its sources, then a second program to grade it. The grader was the broken part: I found 4 problems, fixed 3, and one is still open.
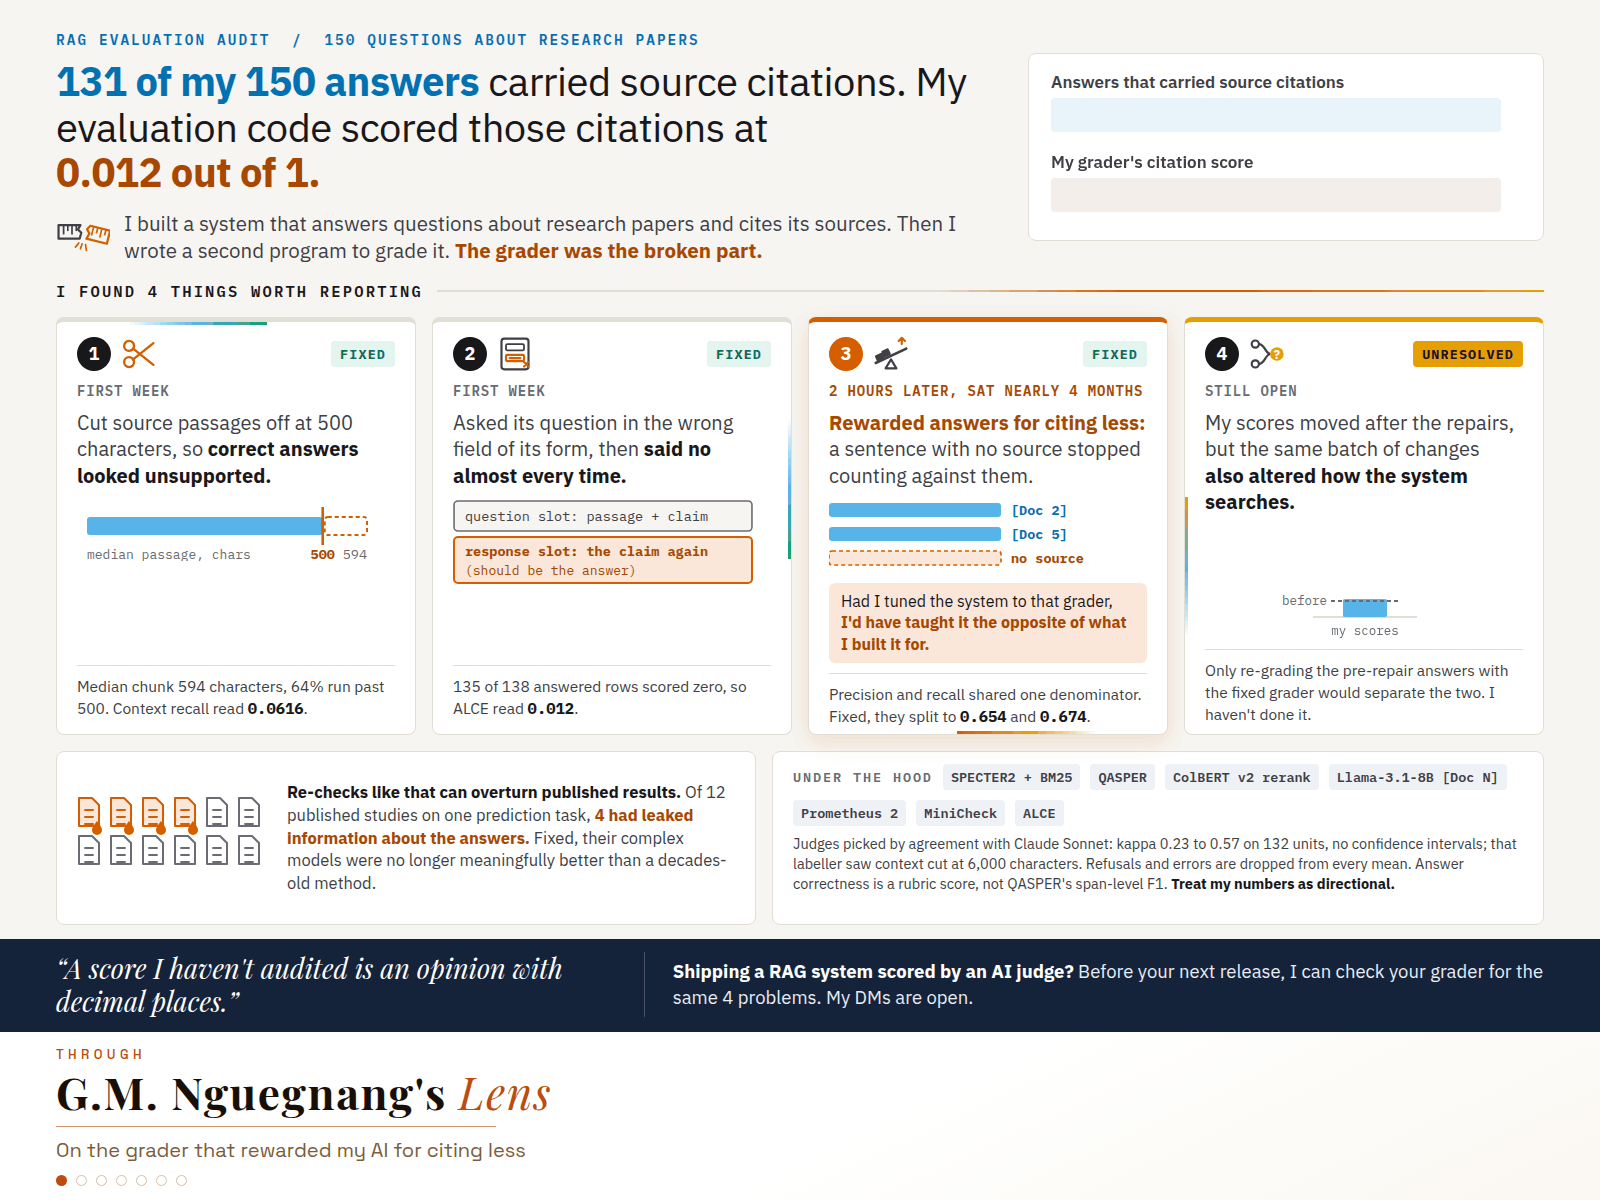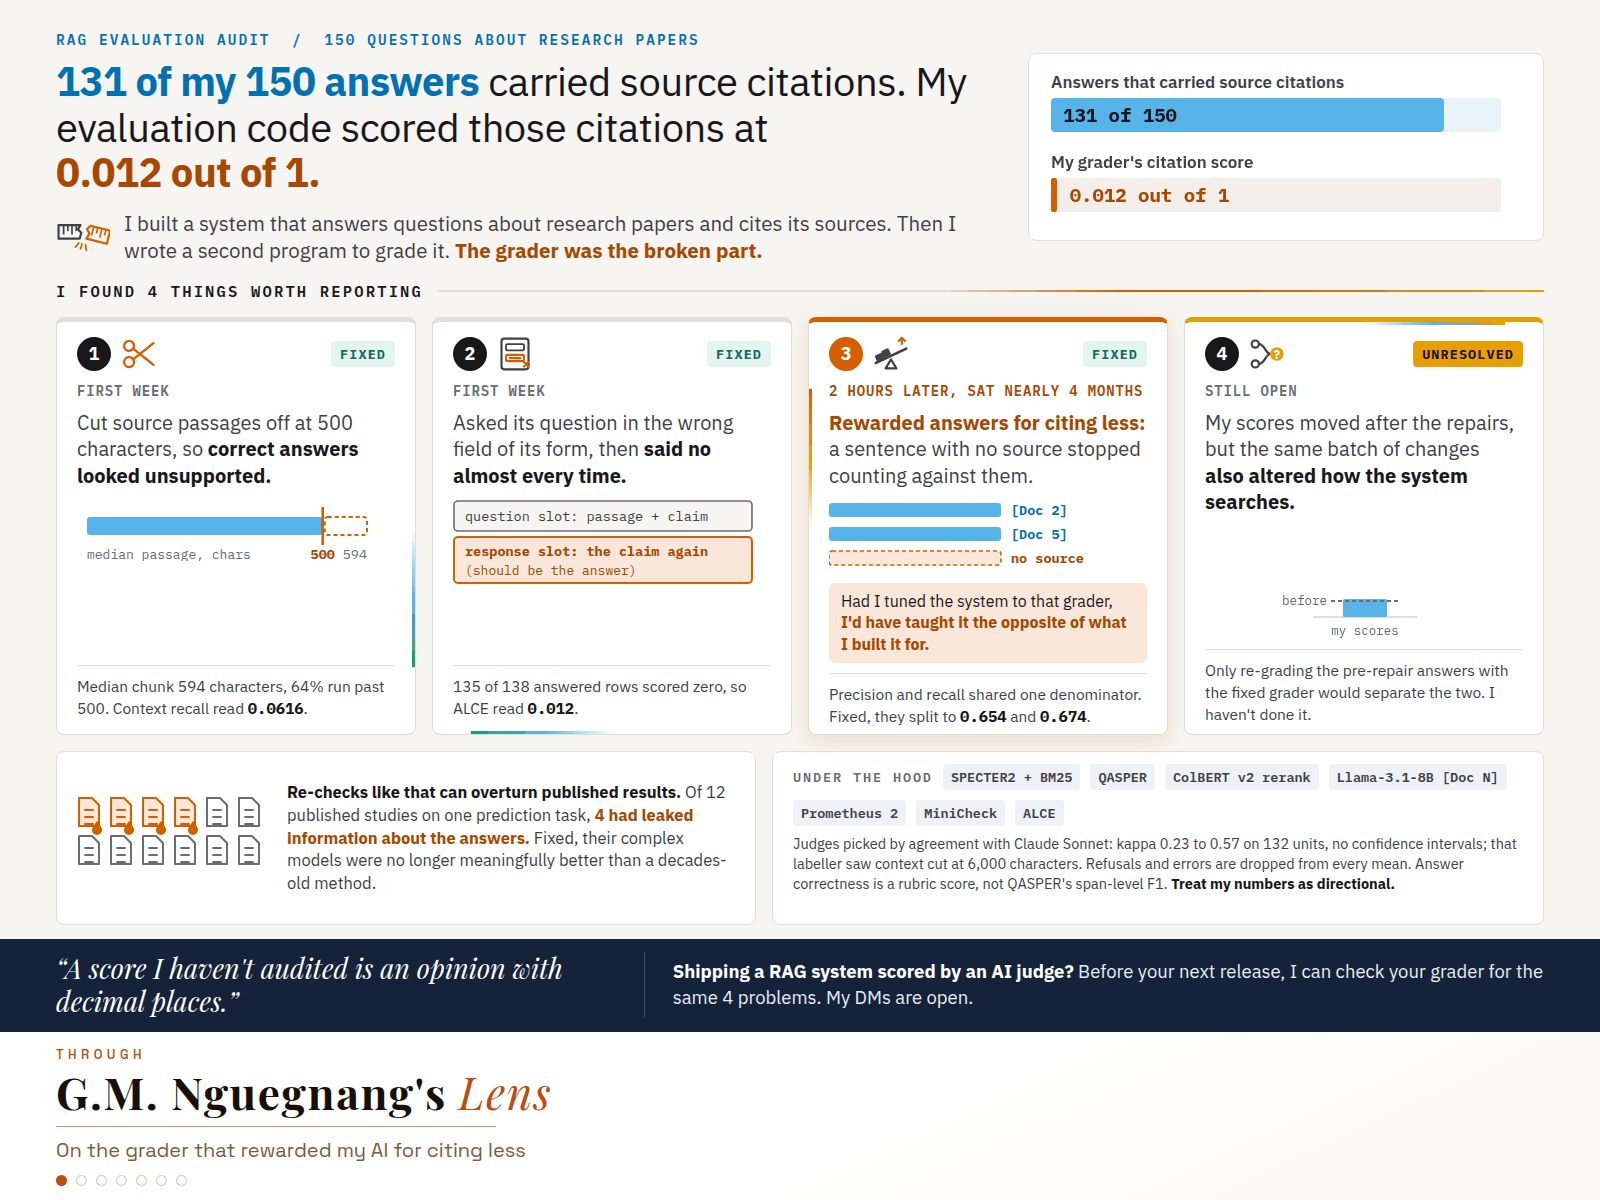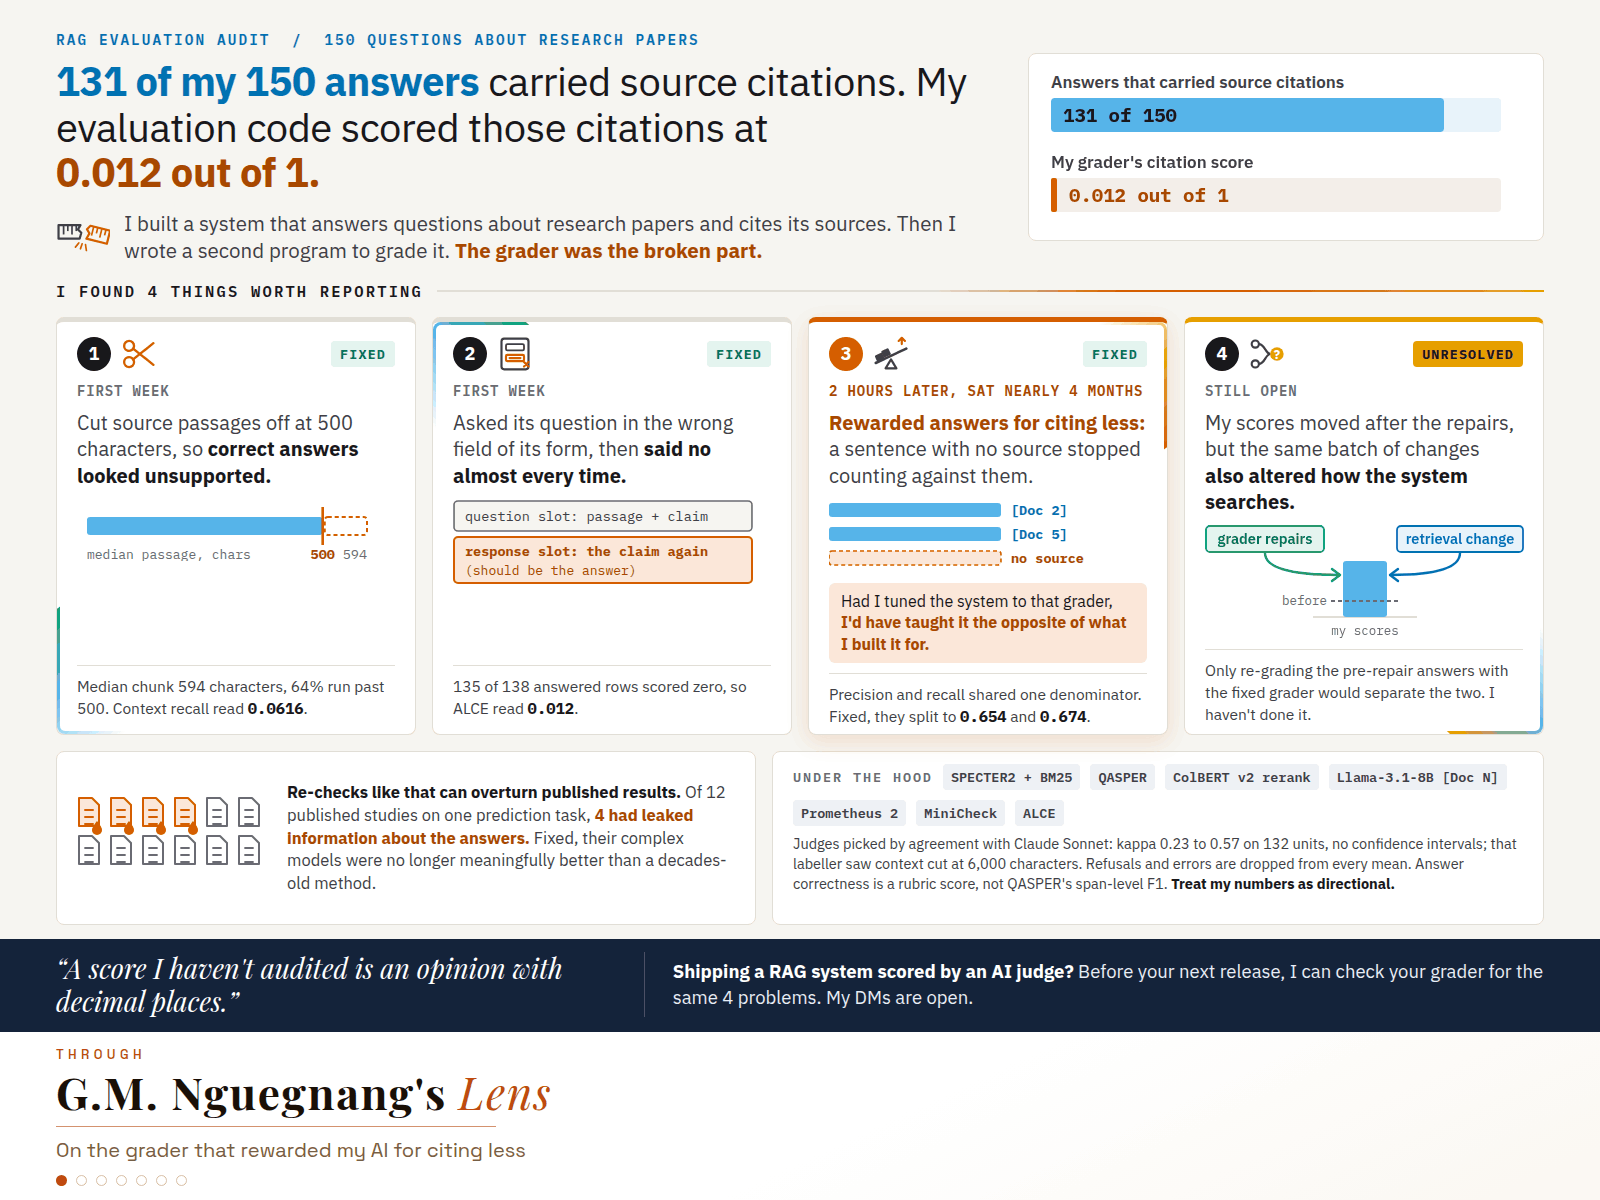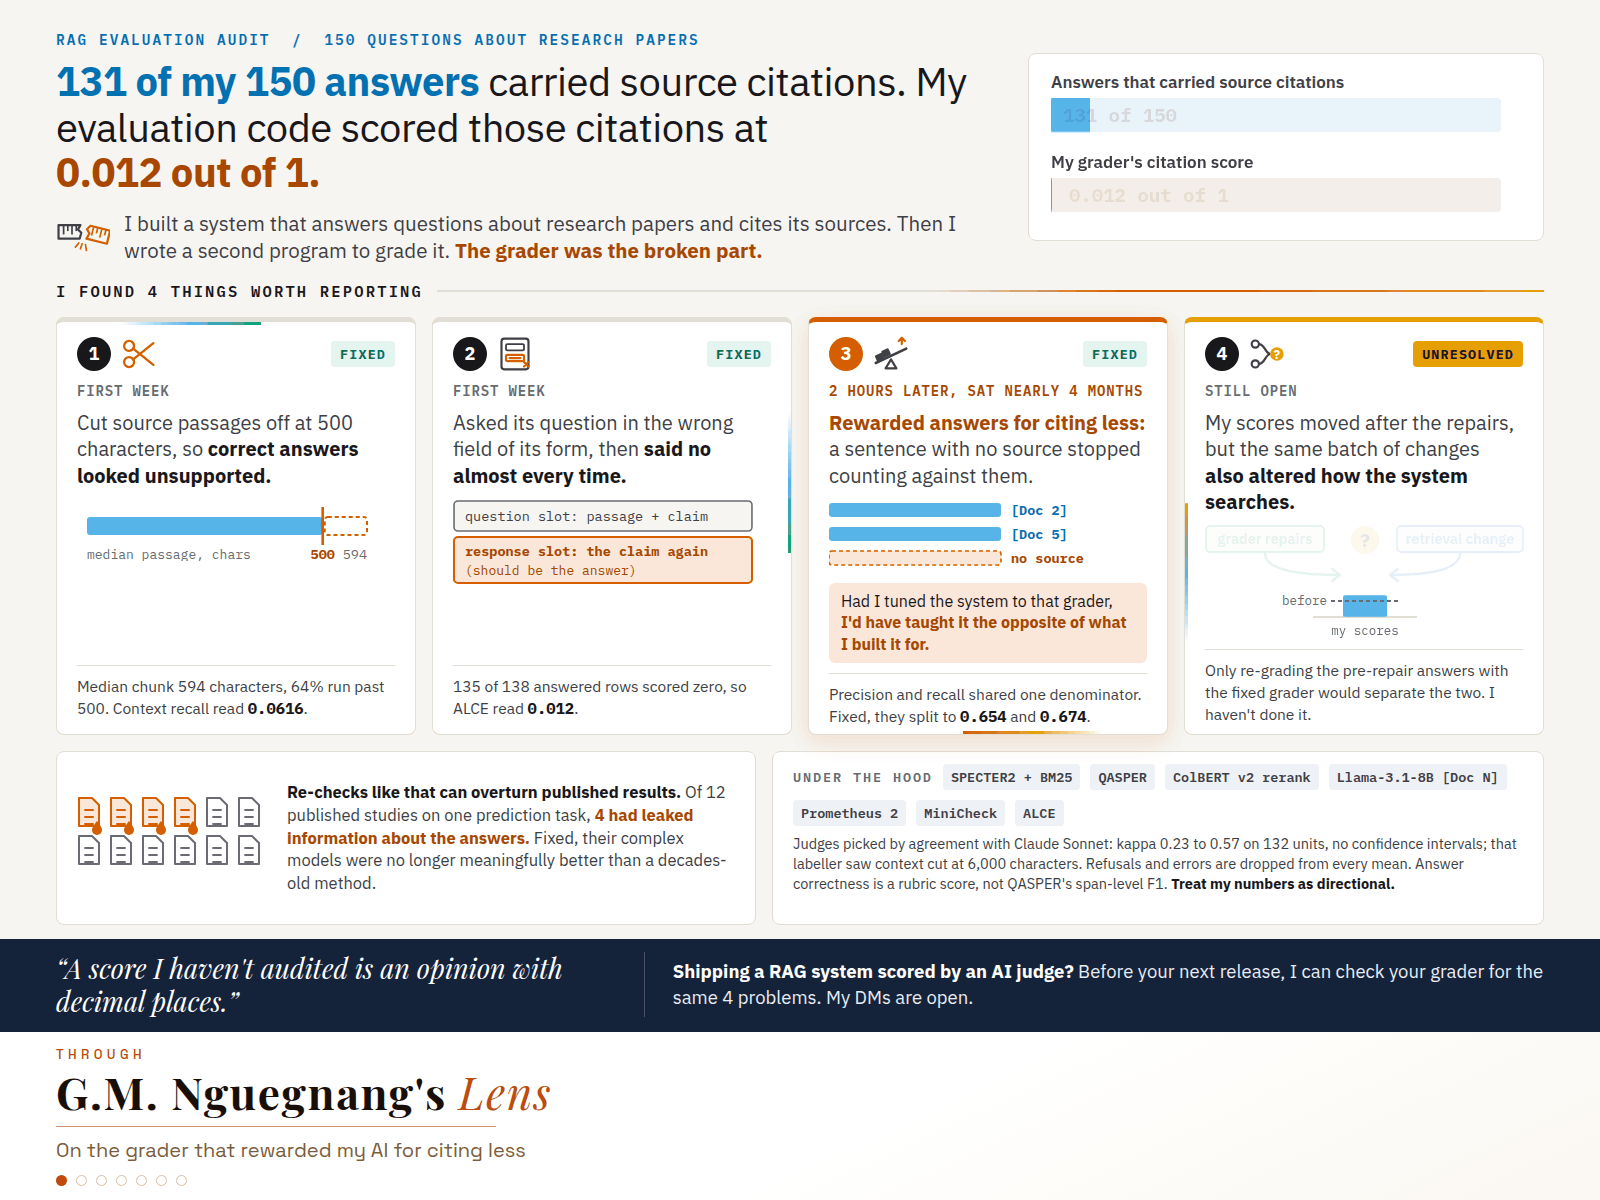
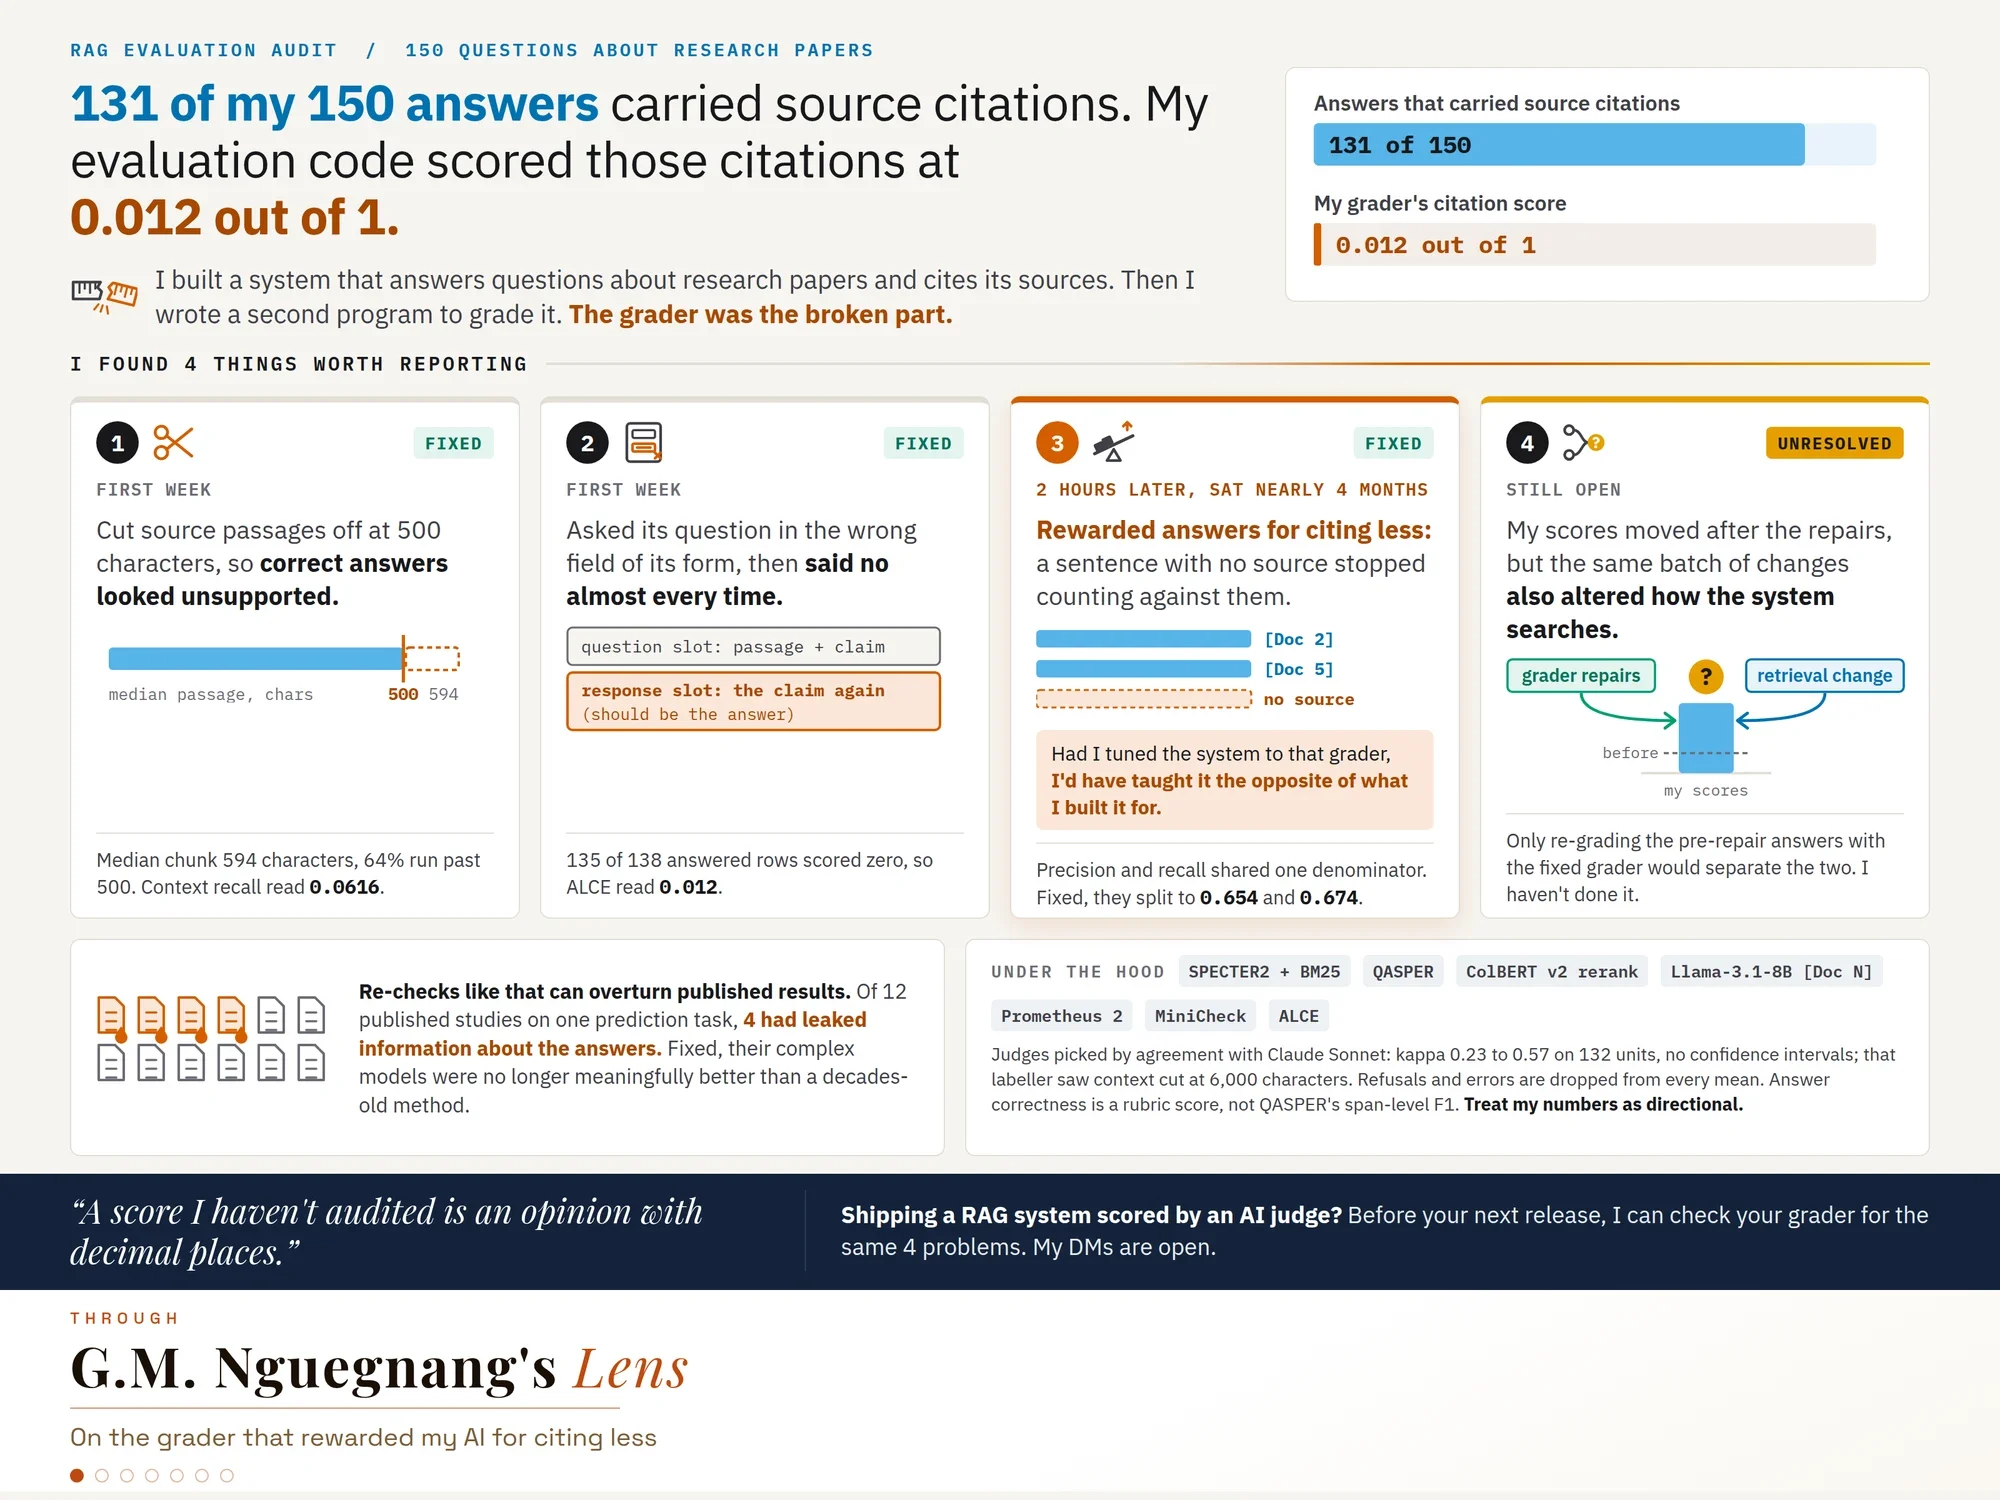
131 of my 150 answers carried source citations. My evaluation code scored those citations at 0.012 out of 1.
I built a system that answers questions about research papers and cites its sources. Then I wrote a second program to grade it.
The grader was the broken part.
Why it matters
I found 4 things worth reporting.
In its first week, my grader cut source passages off at 500 characters, so correct answers looked unsupported. It also asked its question in the wrong field of its form, then said no almost every time.
I fixed both. Two hours later I introduced the third bug, and it sat in my grader for nearly four months.
It rewarded answers for citing less: a sentence with no source stopped counting against them. Had I tuned the system to that grader, I’d have taught it the opposite of what I built it for.
The 4th I can’t resolve. My scores moved after the repairs, but the same batch of changes also altered how the system searches. Only re-grading the pre-repair answers with the fixed grader would separate the two, and I haven’t done it.
Re-checks like that can overturn published results. When researchers re-checked 12 published studies on one prediction task, 4 had leaked information about the answers into what the models learned from. Fixed, their complex models were no longer meaningfully better than a decades-old method.
A score I haven’t audited is an opinion with decimal places.
How it works
SPECTER2 and BM25 over QASPER, ColBERT v2 reranking, Llama-3.1-8B citing [Doc N]. Judges: Prometheus 2 and MiniCheck. Citation metric: ALCE.
Fault 1: c[:500] truncation before context-recall and faithfulness scoring. Median chunk 594 characters, 64% run past 500. Context recall read 0.0616.
Fault 2: the entailment check put the claim in Prometheus 2’s response slot, which expects the graded answer. 135 of 138 answered rows scored zero, so ALCE read 0.012.
Fault 3: precision and recall shared one denominator, and a code comment credited it to the ALCE paper. ALCE averages recall over statements, precision over citations. Mine were identical on all 128 scored rows; fixed, they split to 0.654 and 0.674.
After dropping RAGAS, I picked each metric’s judge by agreement with a second AI judge, Claude Sonnet: kappa 0.23 to 0.57, fair to moderate, on 132 units, no confidence intervals. That labeller saw context cut at 6,000 characters, the same class of bug as Fault 1. Its labels need redoing with full context.
Refusals and errors are dropped from every mean, so fixing a refusal can lower a mean. Answer correctness is a rubric score, not QASPER’s span-level F1, which I don’t yet compute. Treat my numbers as directional.
Shipping a RAG system scored by an AI judge? Before your next release, I can check your grader for the same 4 problems. My DMs are open.