AI Engineering & Agentic AI
Agentic systems and retrieval
6 projects covering production deployment, model alignment, retrieval research, and frontier model consulting. Each one ends in a number, a commit, or a live URL. Open a project for the full case study.
-
Multi-agent · deployed
A planner asks a supply question in plain English. The system does the arithmetic exactly rather than guessing at it, and stops for a manager on anything above $10,000.
99% held-out intent accuracy · 168 tests · 10 business intents
A LangGraph agent routes the question to 1 of 7 exact solvers (OR-Tools, CVXPY, SciPy) or a pgvector CRAG pipeline. Typed Pydantic inputs stand between the model and the solvers, and a human gate pauses any decision above $10,000 until a manager approves it.
-
Cloud deployment · production
Agentic ERP: deployment infrastructure
AKS · Bicep IaCThe pipeline that puts the copilot on live infrastructure, plus the 6 checks that have to pass before any release reaches a user.
Bicep IaC · Kustomize overlays · 6-check smoke test · OTel
Every push runs 6 CI jobs, including a red team, then hands the new images to a deploy that waits for a reviewer's approval. 7 Bicep modules describe the Azure stack, and a 6-check smoke test runs after every rollout.
-
Model alignment research · SFT + DPO
Financial QA alignment via SFT, RLAIF, and DPO
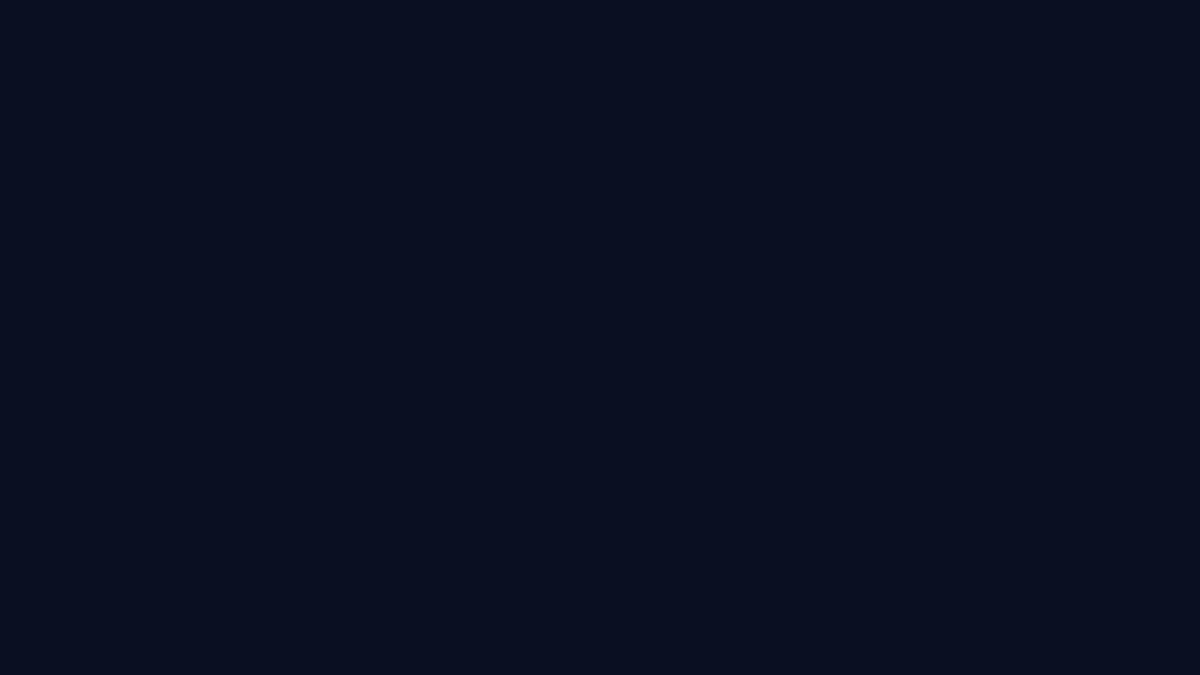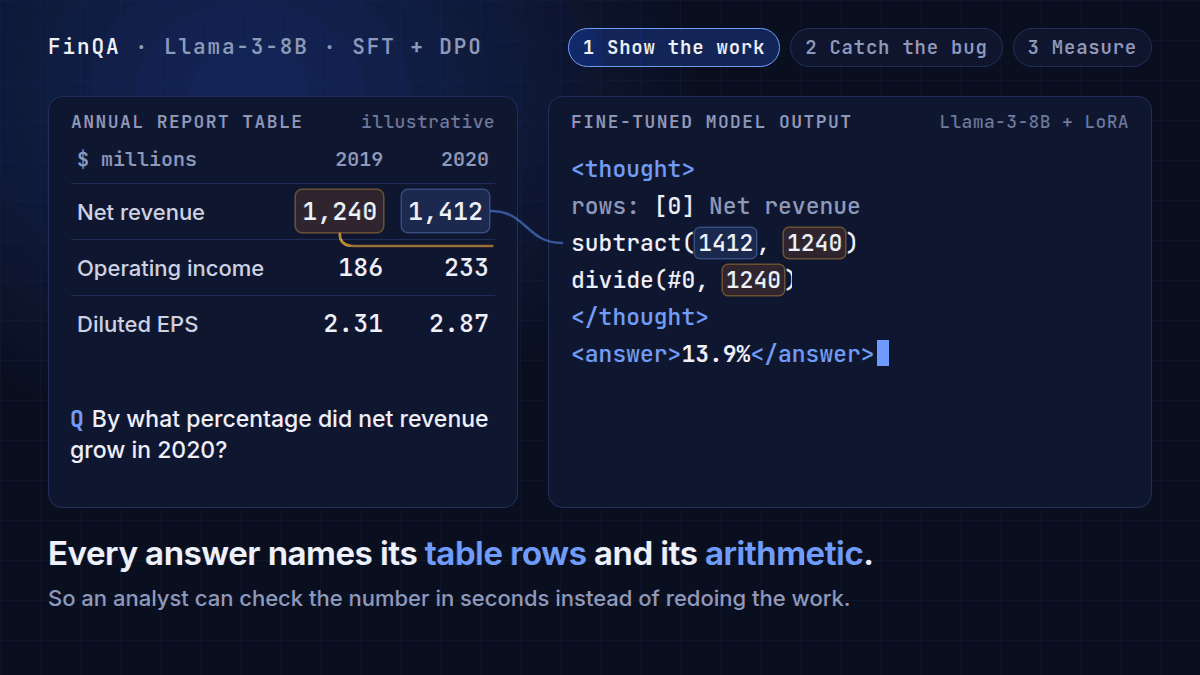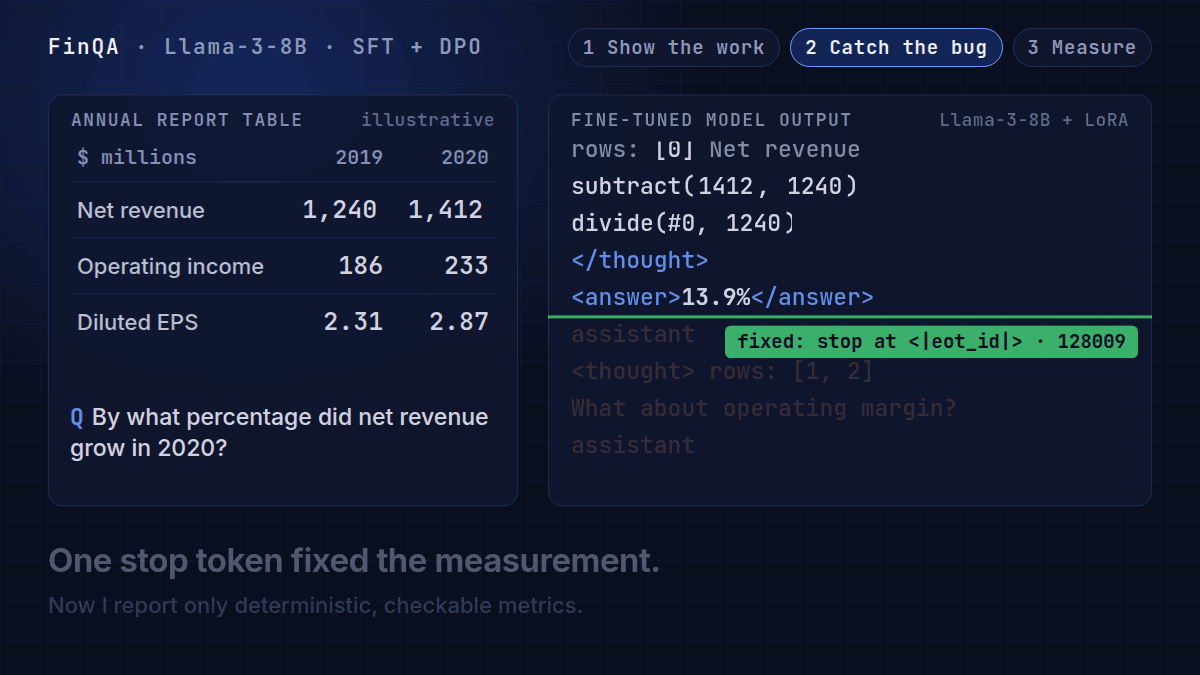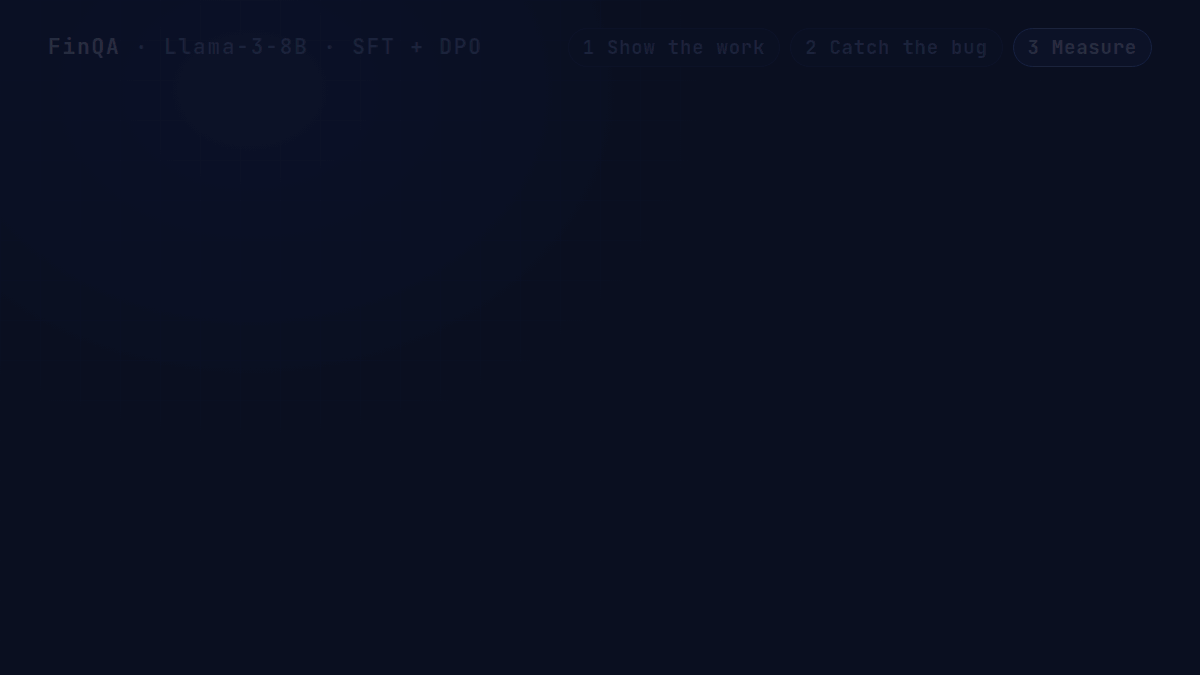
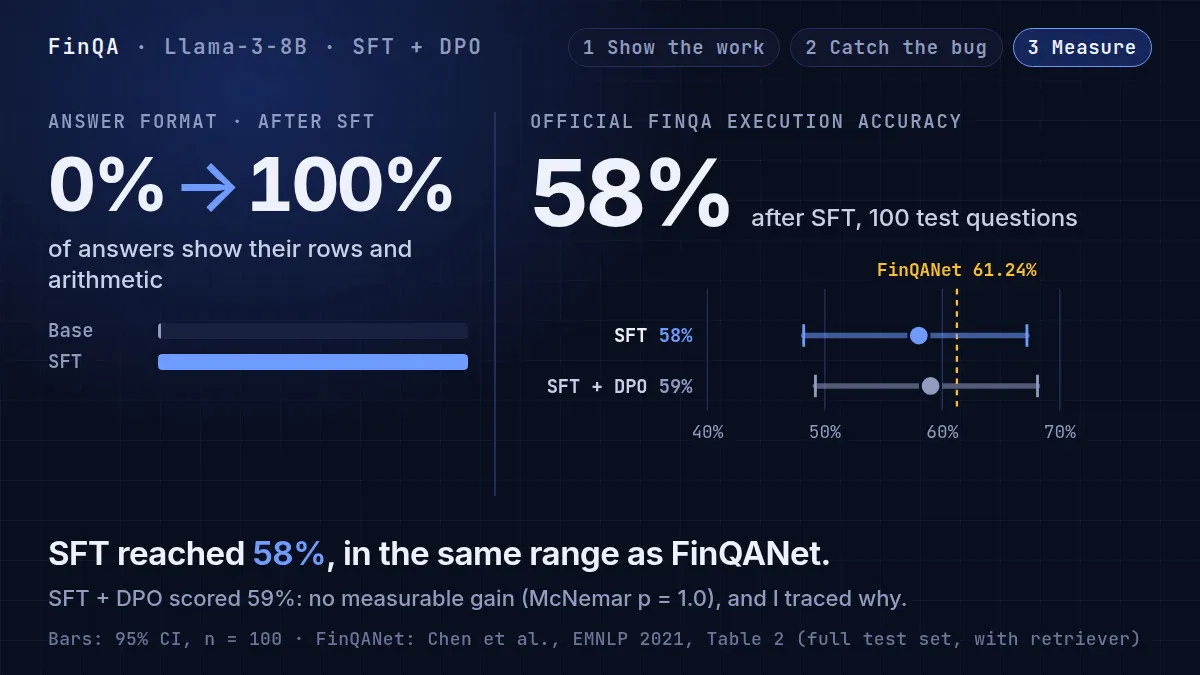
Llama-3-8B · FinQAI taught an 8-billion-parameter model to show its working on financial questions, and I caught a measurement bug that had made my own results look worse than they were.
FinQA execution accuracy 58% (100 test questions) · Answer format 0% to 100%
SFT with LoRA on one RTX 4090, then 1,647 preference pairs labeled by Zephyr-7B-β and DPO. SFT+DPO scored 59% against 58% for SFT (McNemar p = 1.0), and I traced that null result to 3 causes.
-
Production RAG · deployed
Ask a question about a body of research papers and get an answer with its sources attached. It runs as two Docker services on a GPU machine.
ALCE citation precision 0.654 · ~47,800 indexed chunks · 50 → 7 passages
FastAPI and Chainlit in a two-service Docker Compose stack, published to GHCR on every push. There is no Python environment to set up and no index to download by hand.
-
Retrieval research · ongoing
Hybrid RAG for cited answers over research papers
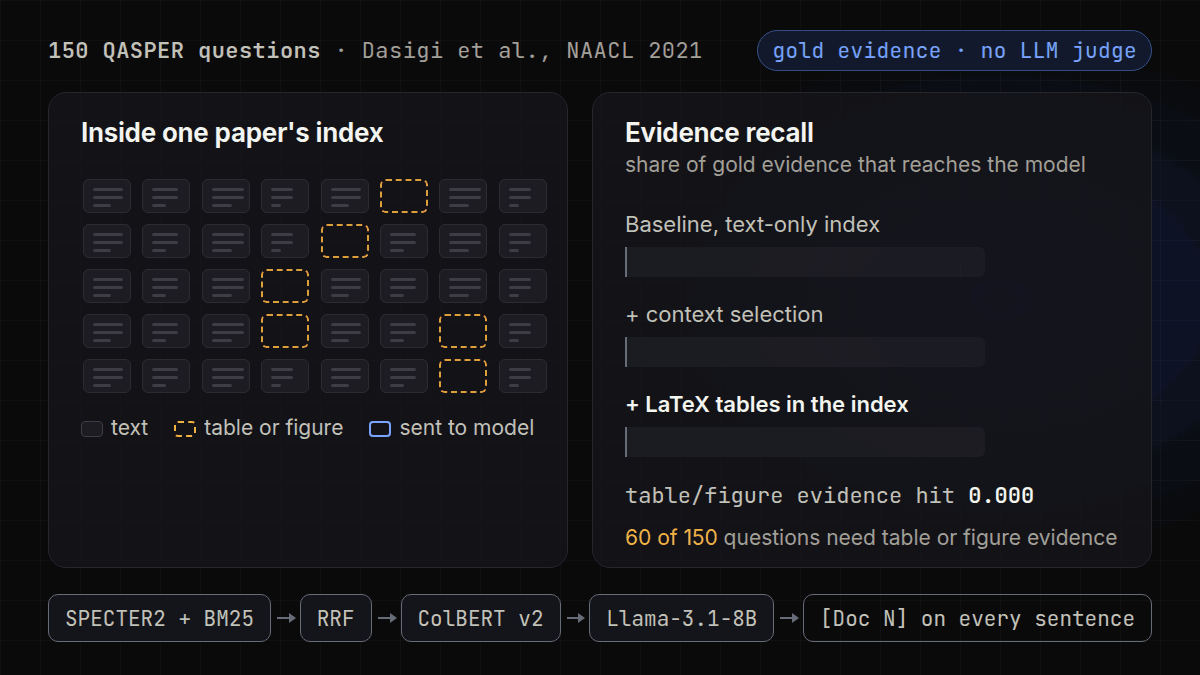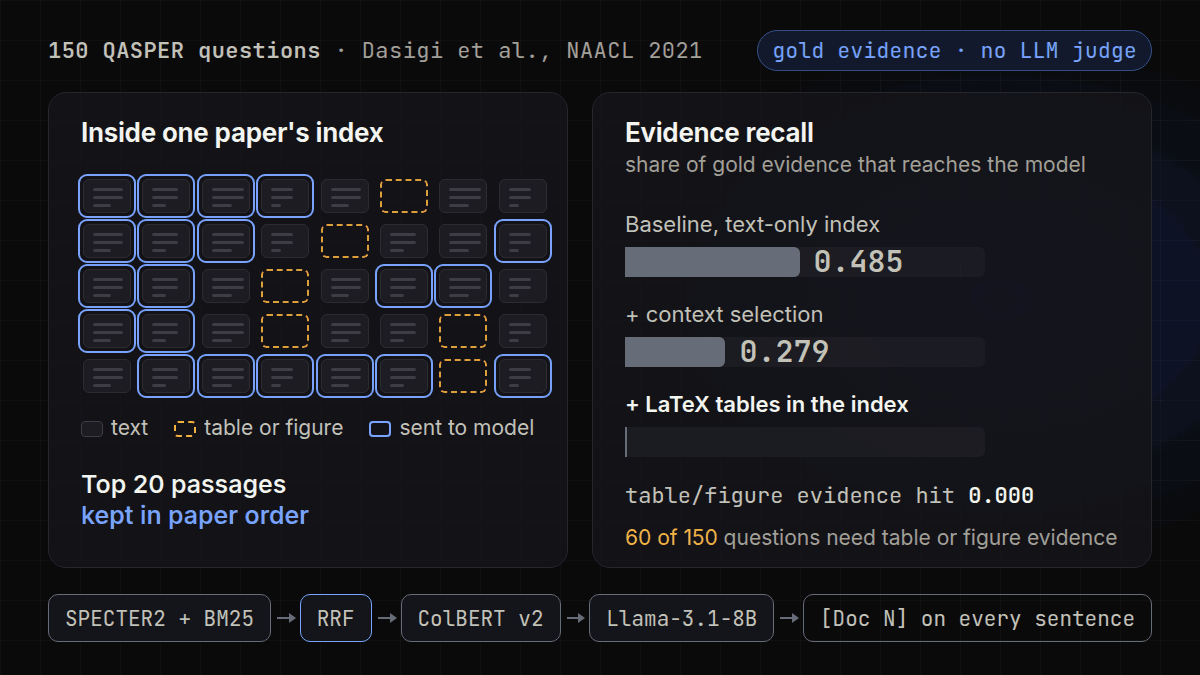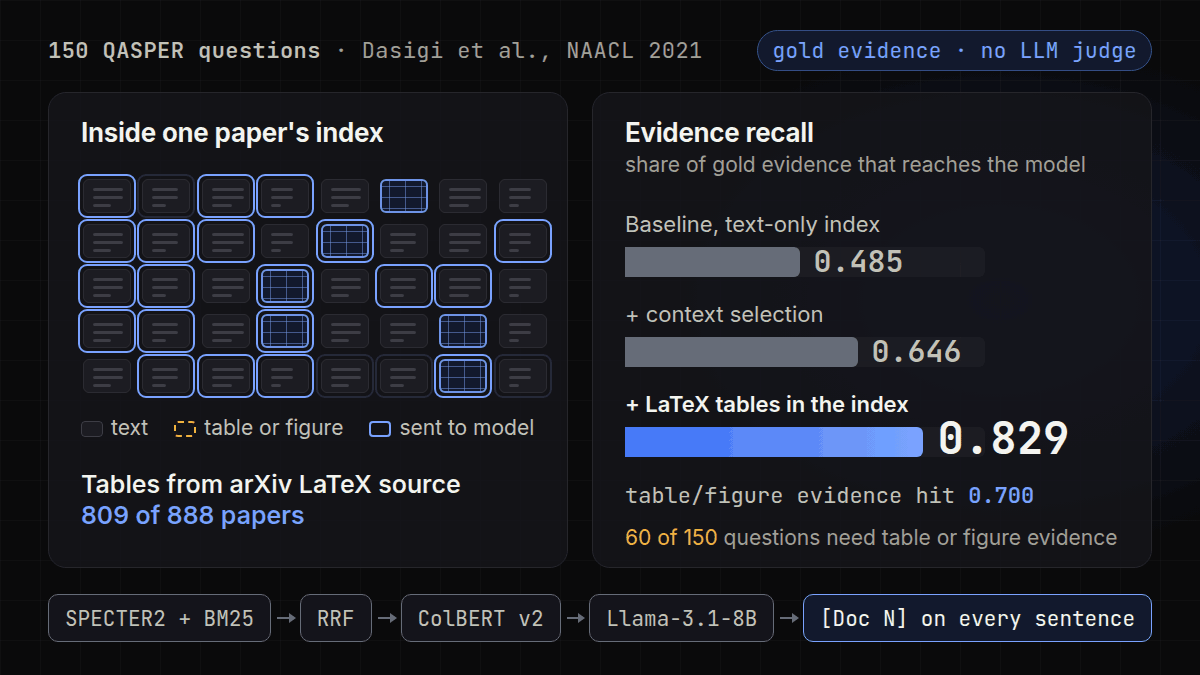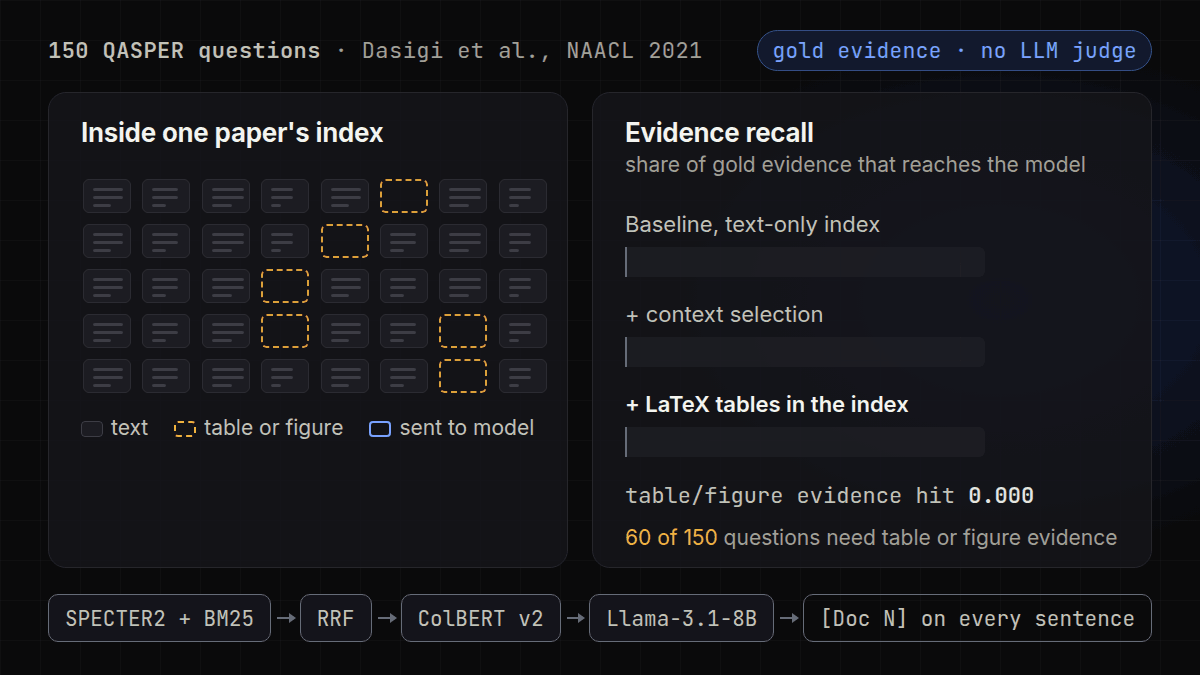
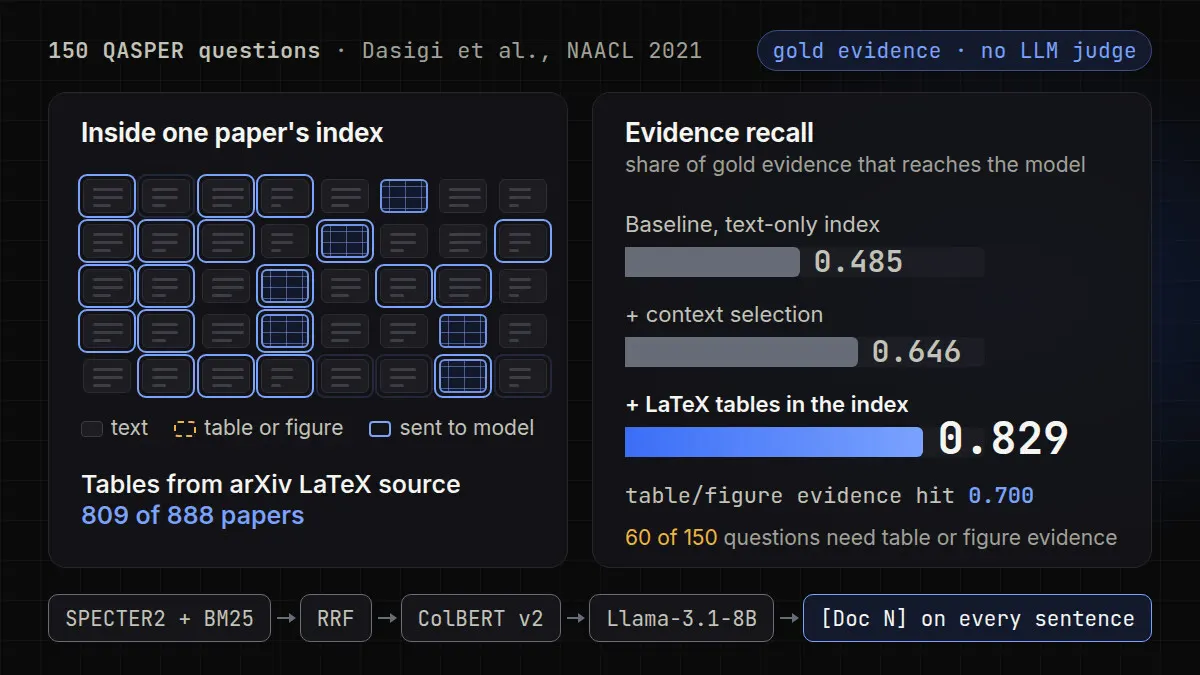
QASPER benchmarkA pipeline that answers questions about research papers with a citation on every sentence, plus an audit of my own evaluation code.
Evidence recall 0.485 to 0.829 · 150 questions · no LLM judge
SPECTER2 and BM25 retrieval, ColBERT v2 ranking, and Llama-3.1-8B generation. Table bodies recovered from arXiv LaTeX for 809 of 888 papers.
-
Frontier model alignment · active consulting
Making frontier models better at hard science problems, and designing the scoring so the improvement can be measured rather than asserted.
RLHF · RLVR · Rubric criteria · Chain-of-Thought
RLVR where the answer is objective, RLHF where it is not, and rubric criteria in between for graded scoring. Plus agent trajectory analysis and the preference datasets that feed SFT and DPO.